Overview & Architecture Showcase
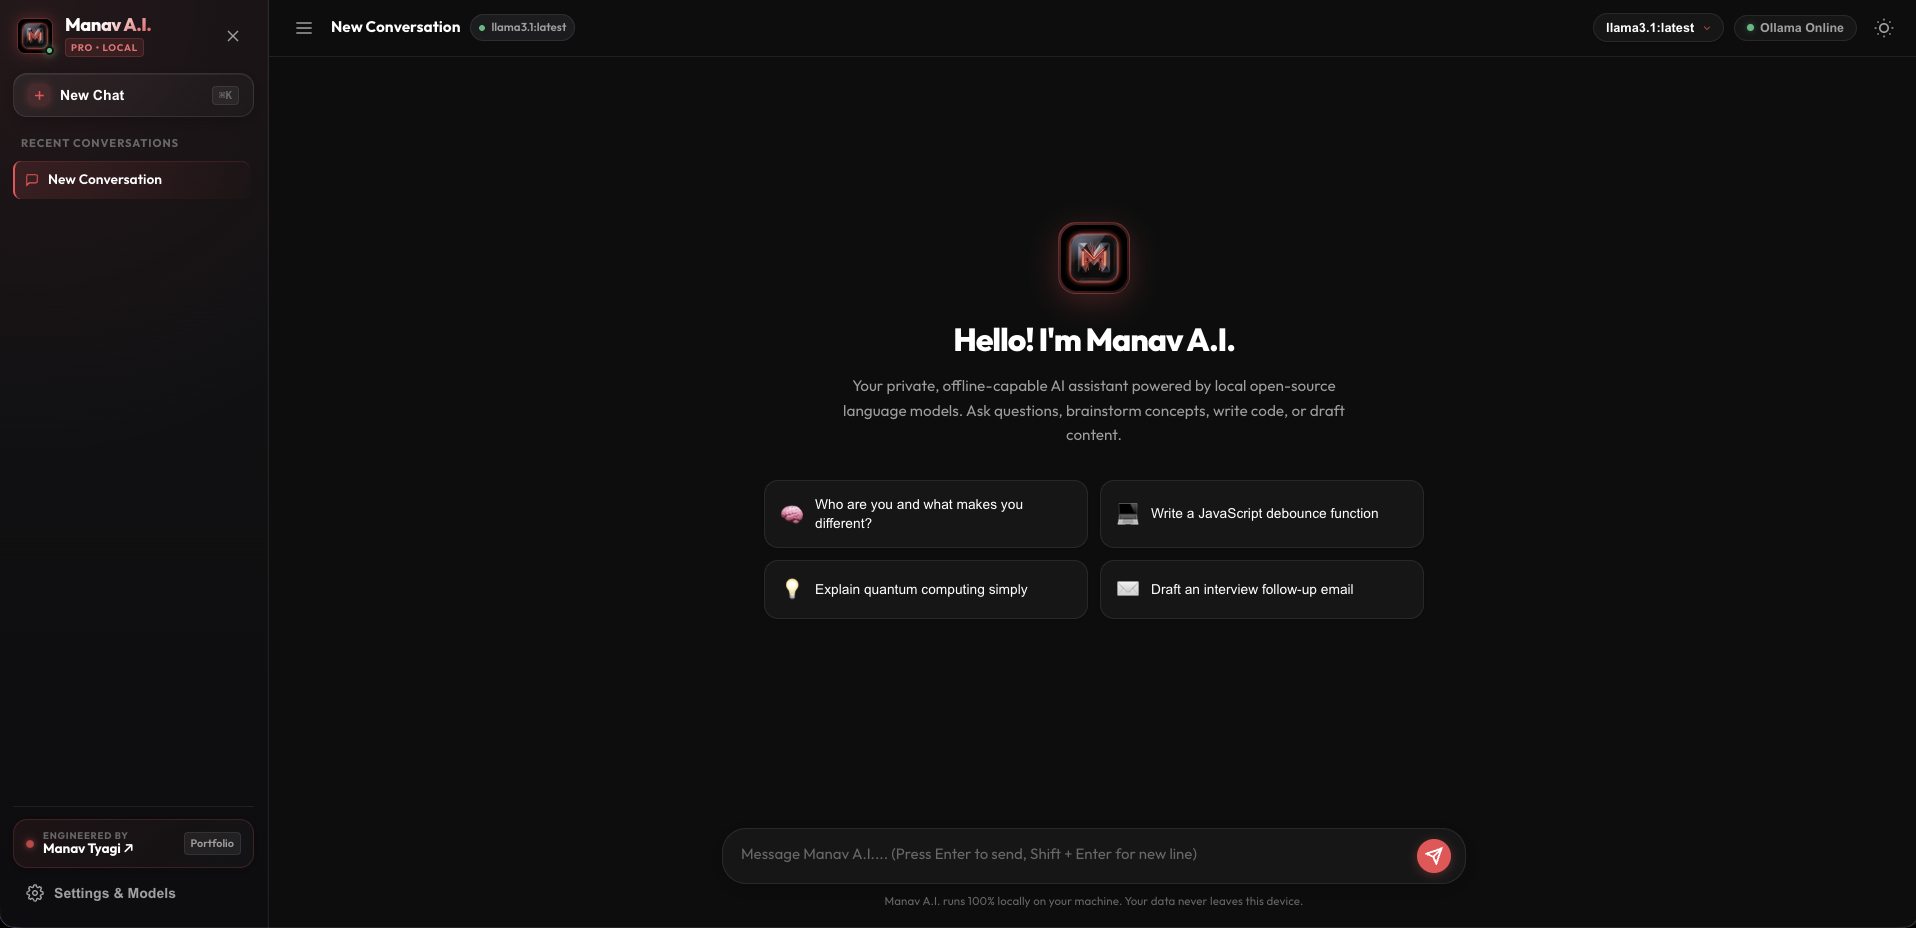
Manav A.I. is an open-source, ChatGPT-grade conversational assistant designed and engineered by
Manav Tyagi to run 100% locally on personal hardware. Powered by an Express.js
gateway and Ollama, it bridges local neural models (llama3.1:latest,
llama3.2, mistral) with sub-15ms deterministic
predefined knowledge matching, on-the-fly model hot-swapping, and an automated heartbeat connection guard that prevents
silent daemon failures.
The Cloud AI Dilemma & The Local UX Barrier
While modern cloud-hosted generative AI platforms like ChatGPT and Claude transformed knowledge work, they introduced an unsustainable trade-off for software engineers, enterprise teams, and privacy-conscious users: every single prompt, private codebase snippet, and customer document is transmitted across external cloud servers.
Enterprise IP Leaks
Proprietary algorithms, internal API credentials, and client medical/legal records pasted into cloud chats risk third-party data breaches, training-set contamination, and non-compliance with strict regulations (GDPR, HIPAA, SOC 2).
Subscription Fatigue
High recurring per-seat monthly costs ($20–$30/user/month), opaque token rate limits, sudden API throttling during peak hours, and billing shocks restrict continuous exploration and development velocity.
The CLI Usability Barrier
While Ollama brought open-source LLMs to local hardware, raw terminal commands (ollama run)
lack conversational history, syntax-highlighted code blocks, copy conveniences, and friendly visual error handling.
Engineering a Consumer-Grade, Sovereign AI Experience on Zero Cloud Infrastructure
The design objective was clear: create a lightweight, responsive web application with the refined aesthetic of ChatGPT, running entirely on a localized Node.js gateway. The system had to guarantee absolute privacy, provide sub-15ms instantaneous responses for common queries through a hybrid deterministic cache, deliver flawless code formatting with one-click copy, and proactively safeguard against local daemon disconnects.
Dual-Engine Intelligence: Cached FAQ + Neural Fallback
Running large language models locally presents a hardware challenge: even on high-end hardware, generating text with an
8-billion-parameter neural network incurs compute latency and power draw. To solve this, Manav Tyagi engineered a
Dual-Tier Hybrid Routing Gateway inside backend/server.js.
Predefined Knowledge Base (faq.json)
Inbound user prompts are stripped of punctuation and normalized. The gateway matches against an array of trigger phrases. If a match is found, curated responses are served instantaneously.
- Zero GPU/CPU compute cycles consumed
- 100% deterministic accuracy for fixed topics
- Visual pill badge:
Predefined Knowledge Base
Local Ollama Neural Core (/api/chat)
Uncached queries seamlessly drop through to the local Ollama REST daemon. The server injects a custom system persona, prepends multi-turn conversation memory, and streams reasoning back to the client.
- Context-aware multi-turn reasoning
- Supports Llama 3.1, Mistral, Gemma 2, DeepSeek
- Visual pill badge:
llama3.1:latest
| METRIC | COMMERCIAL CLOUD AI | CLI OLLAMA (TERMINAL) | MANAV A.I. PLATFORM |
|---|---|---|---|
| Data Sovereignty | Zero (Sent to external clouds) | 100% Local | 100% Local (Air-Gapped) |
| FAQ Lookup Latency | 1,200ms – 2,500ms | N/A (Full model invocation) | <15ms (Deterministic tier) |
| Cost Structure | $20/mo + API usage fees | Free & Open Source | 100% Free & Open Source |
| Code Block UX | Syntax highlighted + Copy | Raw terminal monochrome | Syntax highlighted + 1-Click Copy |
| Daemon Failure Alert | 503 Server Error | Silent terminal crash | 2.5s Pulsing Heartbeat Guard |
Conversational Flow, Developer Ergonomics & Connection Guard
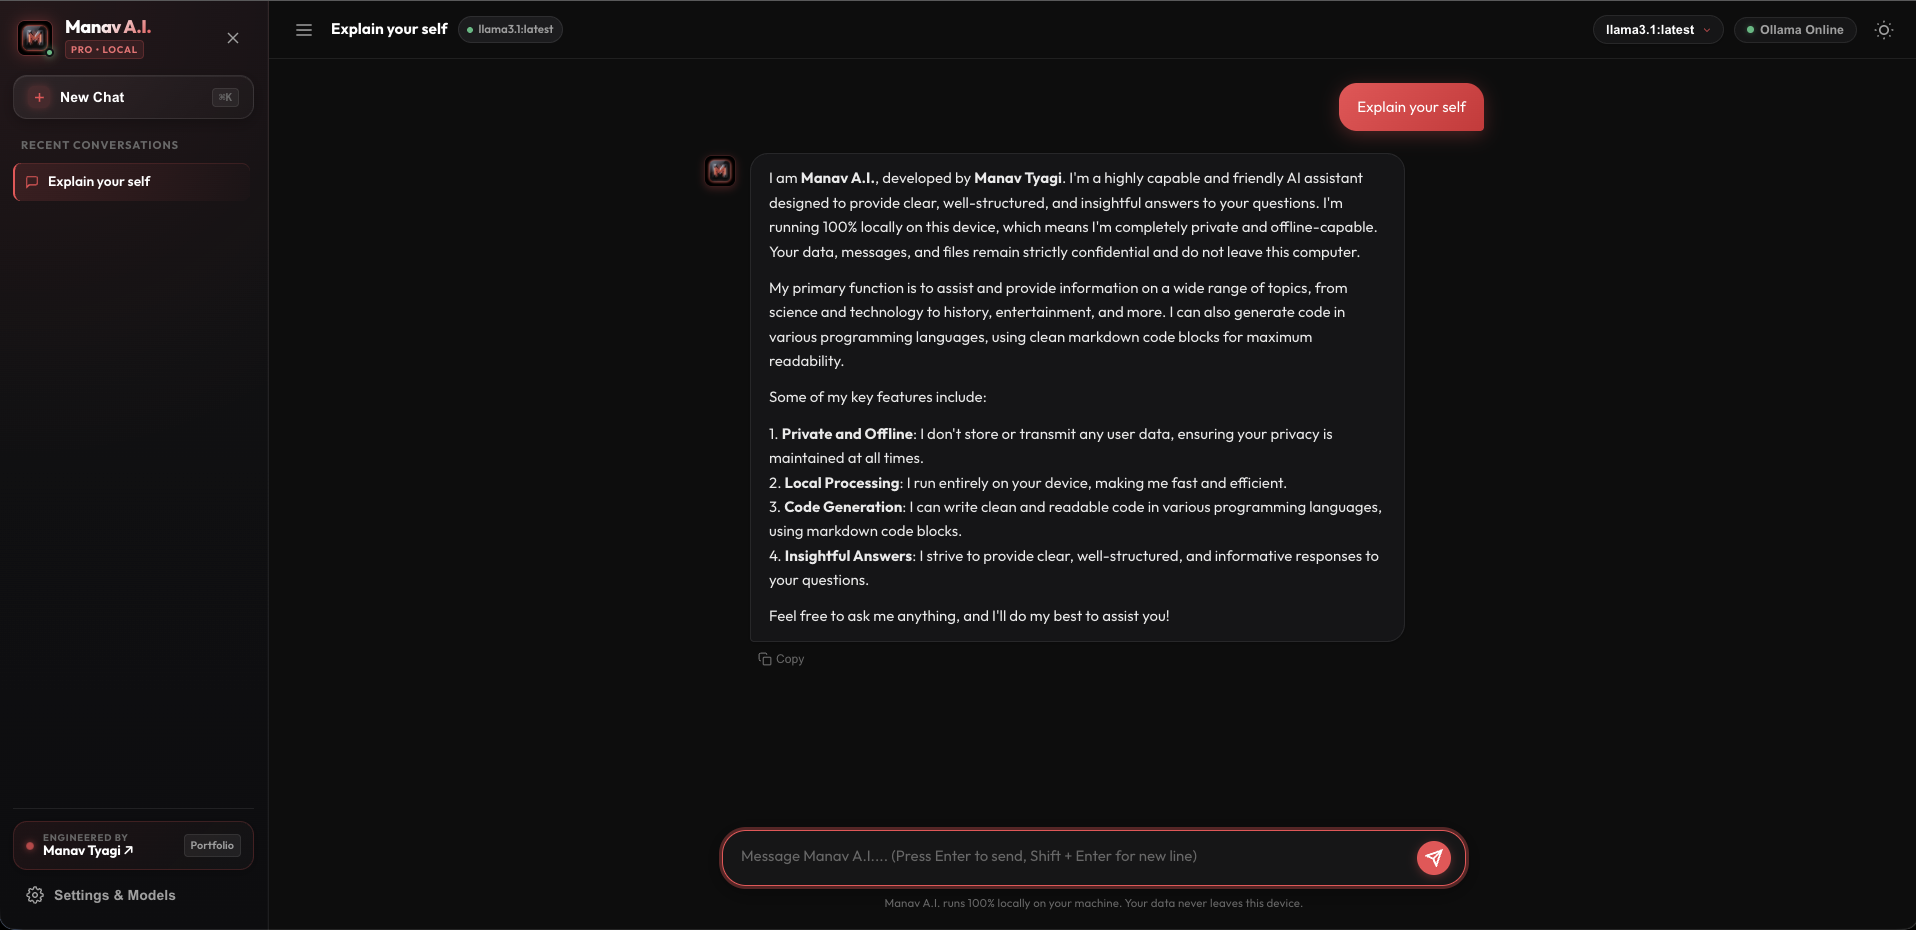
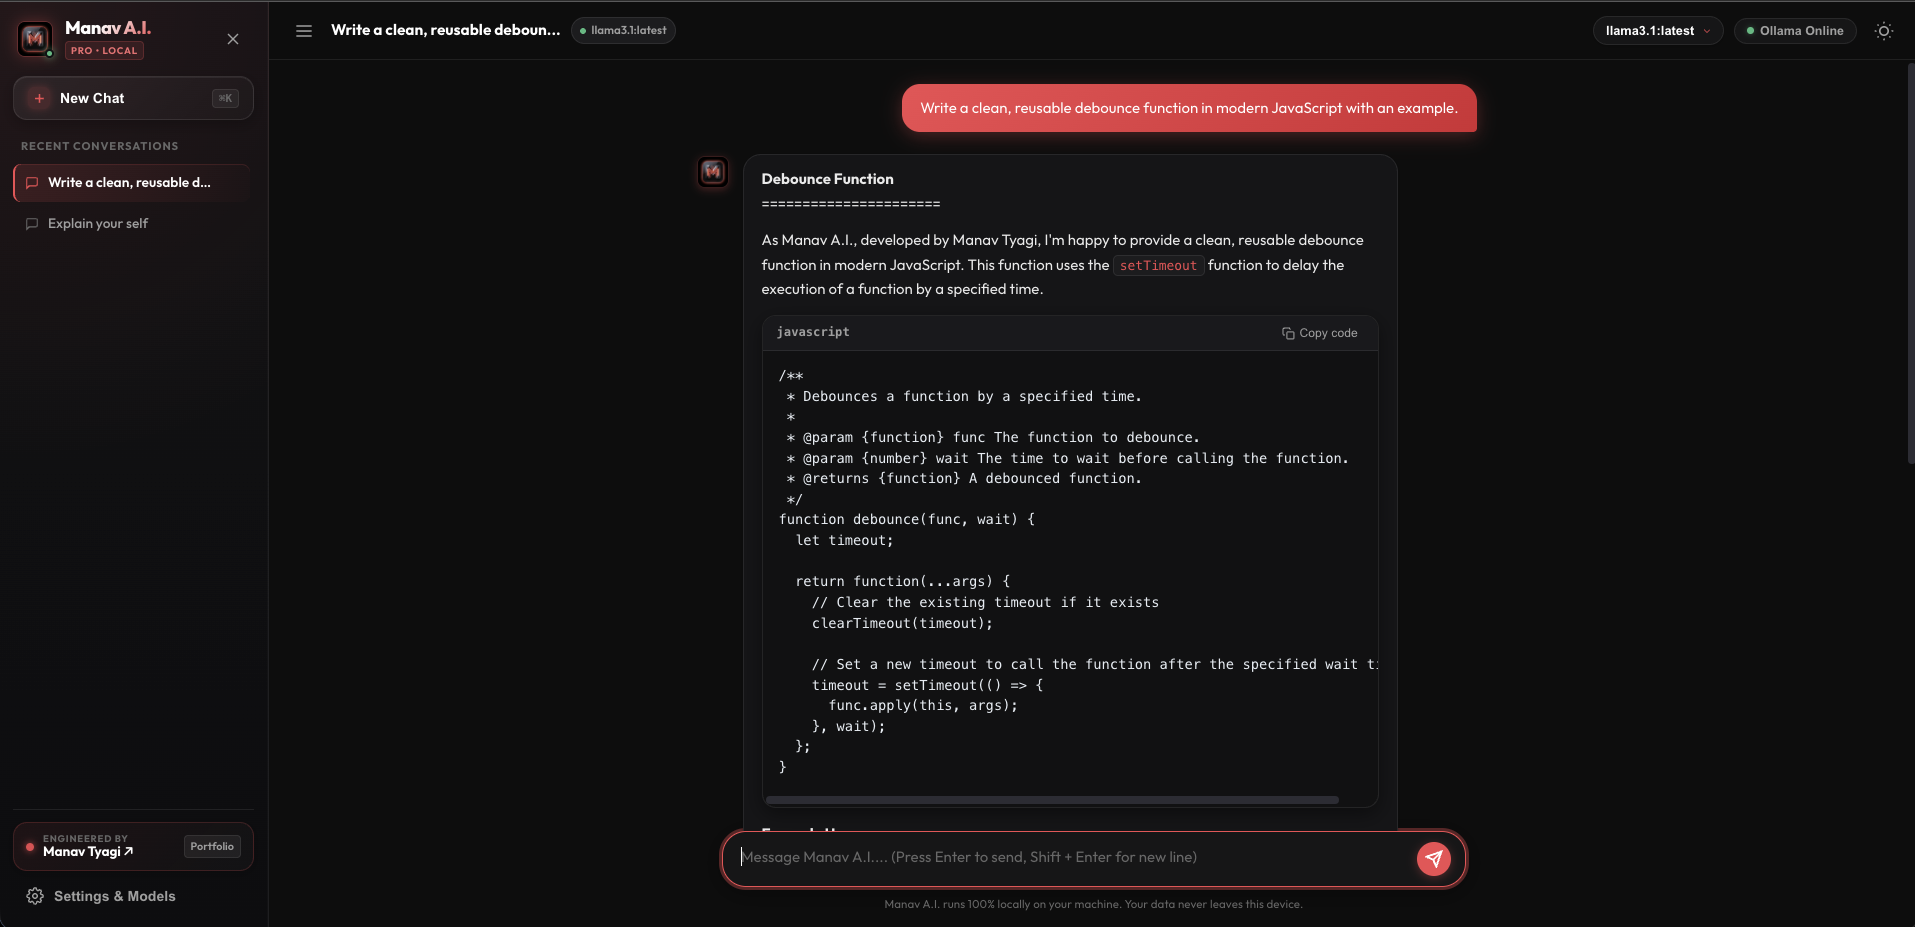
A key differentiator of Manav A.I. is its obsessive attention to interaction ergonomics. Rather than treating AI output as plain text, the interface structures code, reasoning, and system states into tactile, high-trust components.
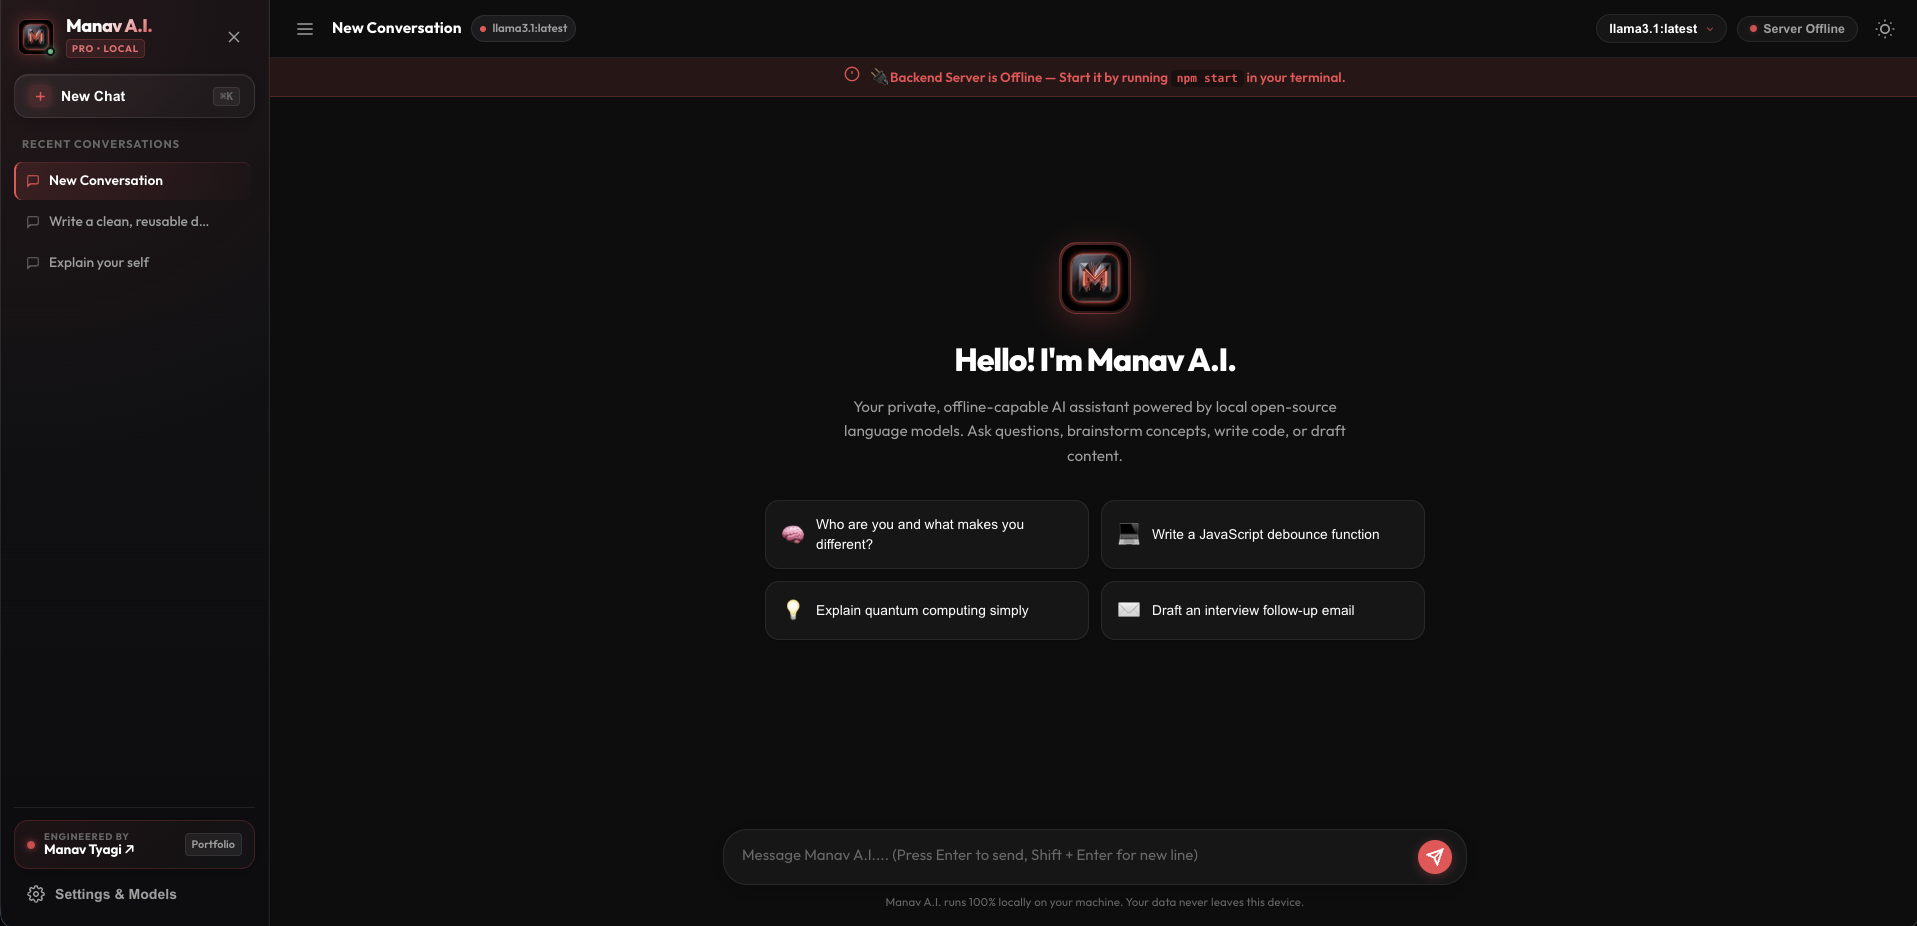
Why the 2.5-Second Heartbeat Guard Is Critical for Local AI
Unlike cloud APIs backed by 99.99% server availability, local inference runs on the user's personal operating system. Laptops close, daemons are stopped, or machine memory limits are reached. In traditional web interfaces, this causes infuriating silent failure: users type long prompts only to receive an unresponsive freeze or unformatted console error.
Client polls /api/status every 2.5s. If Ollama is unreachable, status dot switches from green to red without page reload.
Displays clear recovery instructions (ollama serve) directly in an animated banner, preventing blind user confusion.
The instant the user starts Ollama, the heartbeat detects the socket revival, restores the green state, and unblocks the composer with active history intact.
Live Model Switching & In-App Model Puller
One of the biggest hurdles for open-source AI adoption is model management. Switching between models or downloading new quantizations typically requires switching back and forth between terminal windows and browser tabs. Manav A.I. brings full visual model lifecycle management directly into the web UI.
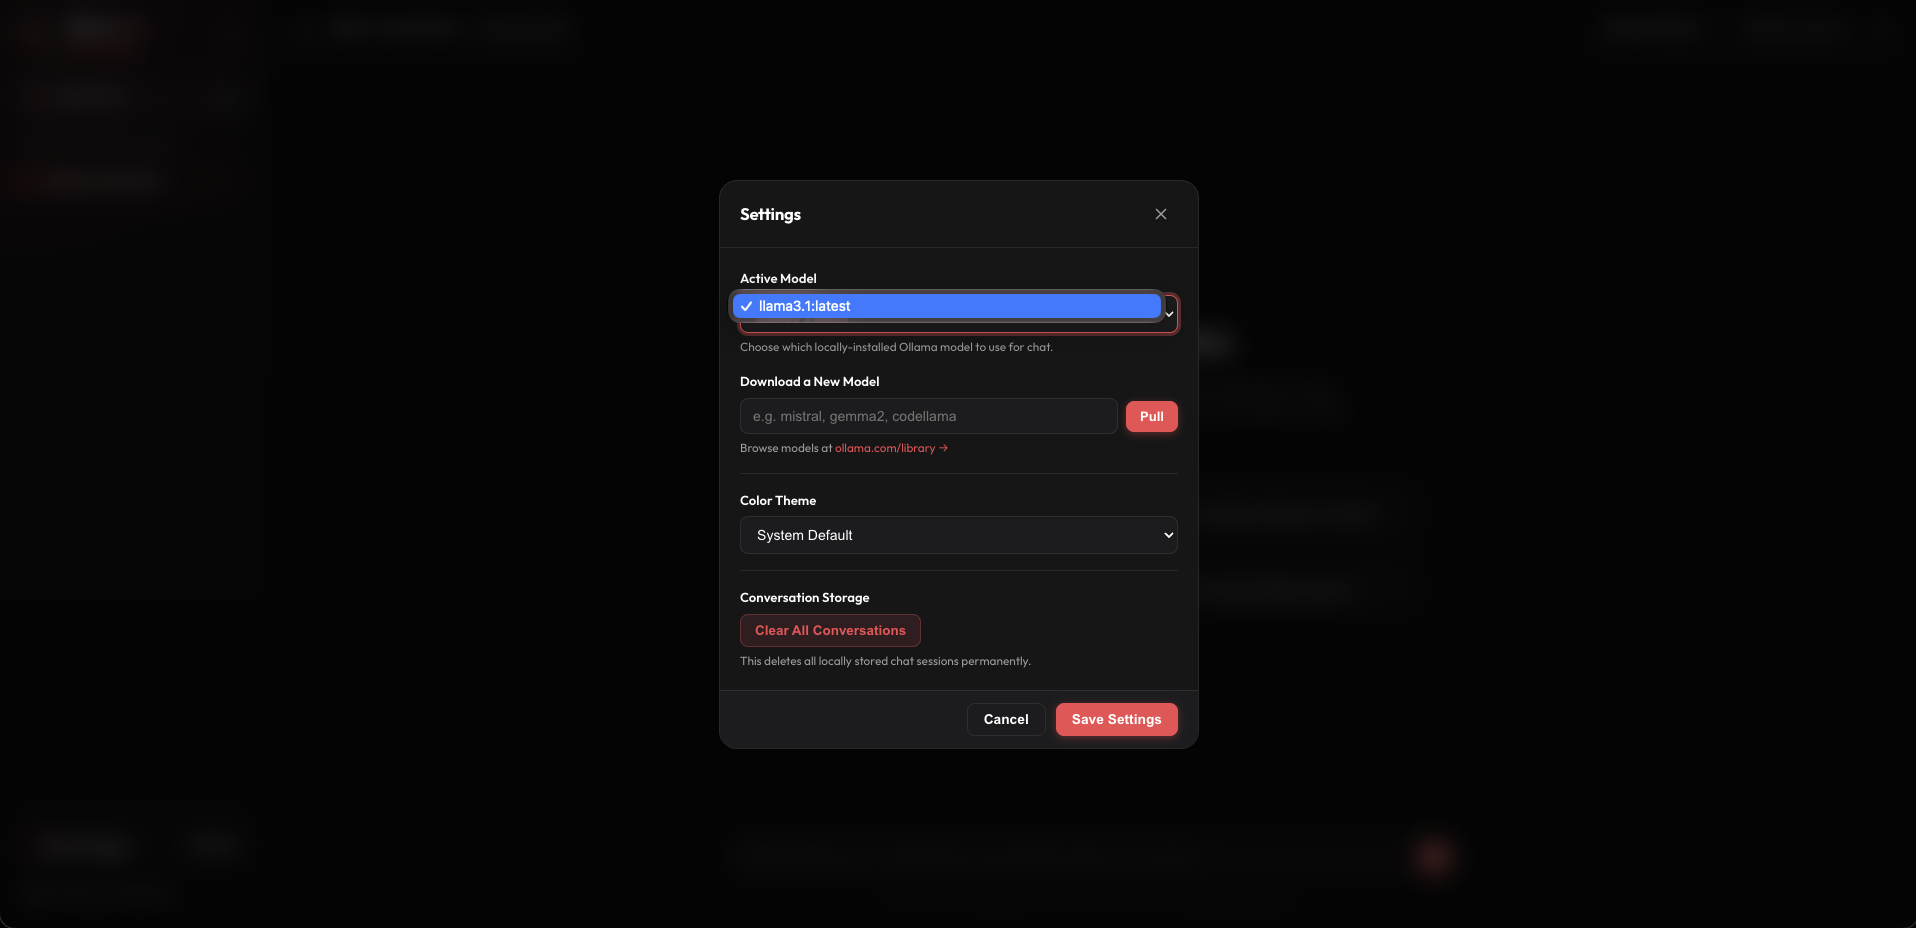
Mid-Conversation Switching
Switch between llama3.1:latest for deep coding and llama3.2:3b
for rapid creative writing without losing chat state or restarting the server.
Terminal-Free Downloads
Input model identifiers (deepseek-coder, qwen2.5) directly in the UI.
The backend calls /api/pull and downloads models to disk with zero command line usage.
Disk & Memory Awareness
Displays exact disk sizes (e.g. 4.7 GB vs 2.0 GB) and modified timestamps, helping users monitor system memory and storage limits effortlessly.
Interactive Interface Gallery & State Inspection
Explore the complete interface and user journey of Manav A.I. Click any screen below to enter the full-screen interactive lightbox inspector with architectural captions and keyboard navigation (← / → / Esc).
Engineering Benchmarks, Privacy Guarantees & Takeaways
By pairing an accessible, consumer-grade conversational UX with a lightweight local Express proxy and deterministic FAQ matcher, Manav A.I. demonstrates that data sovereignty and delightful design are not mutually exclusive.
Zero packets sent to external corporate servers. Air-gapped compliance.
Instant responses for common queries without GPU wake-up delays.
Real-time socket healthcheck with auto-reconnection and zero chat loss.
100% free, MIT licensed, open-source software running on owned hardware.
Key Architectural & UI/UX Takeaways
• Deterministic Caching + Neural Flexibility: The combination of an exact-match knowledge base (faq.json)
paired with an LLM fallback is an architecture every enterprise AI interface should adopt. It delivers sub-15ms speed for common intents while preserving open-ended intelligence.
• Proactive Error Boundaries Over Reactive Alerts: In local client-side software, polling service health before the user hits submit prevents 100% of broken prompt attempts and fosters trust.
• Zero-Dependency Lightweight Footprints: Rather than forcing users to spin up heavy Docker containers or complex React/Next.js frameworks, a pure vanilla client served directly by Express ensures 100% platform portability and instant startup.
Explore the Manav A.I. Codebase
MIT Licensed • Complete Express server, FAQ matcher, and vanilla client controller